Safe Multi-Agent Navigation via
Constrained HJB-Informed Learning

National University of Singapore, Department of Electrical and Computer Engineering
CORE Lab

Abstract

Multi-agent navigation in unknown and cluttered environments has broad applications, yet remains fundamentally challenging. In particular, dense agent-agent and agent-obstacle reactive interactions can exacerbate the inherent competition between collision-avoidance constraints and goal-reaching objectives. Most existing approaches mitigate this by applying per-step safety filtering on top of a predefined goal-reaching controller or by designing heuristic loss functions that penalizes safety constraints violation gradient. While effective in sparse environments, these methods still suffer from overly-conservative behaviors when interactions become dense. To overcome these limitations, we propose HJB-GNN, a Hamilton-Jacobi-Bellman (HJB)-based learning framework that jointly learns a graph neural network (GNN)-parameterized control barrier function for explicit safety enforcement, a distributed GNN-based navigation policy, and a value function that induces goal-reaching behavior. By exploiting the analytical solution of the constrained HJB equation, the proposed method derives graph-dependent Lagrange multipliers that adaptively balance collision-avoidance and goal-reaching across diverse multi-agent navigation scenarios. Moreover, HJB-GNN supports centralized training with distributed deployment. Extensive simulations and real-world experiments with Crazyflie drone swarms demonstrate its superior safety and goal-reaching performance, as well as strong scalability and generalizability to large-scale teams operating in previously unseen, dense environments.
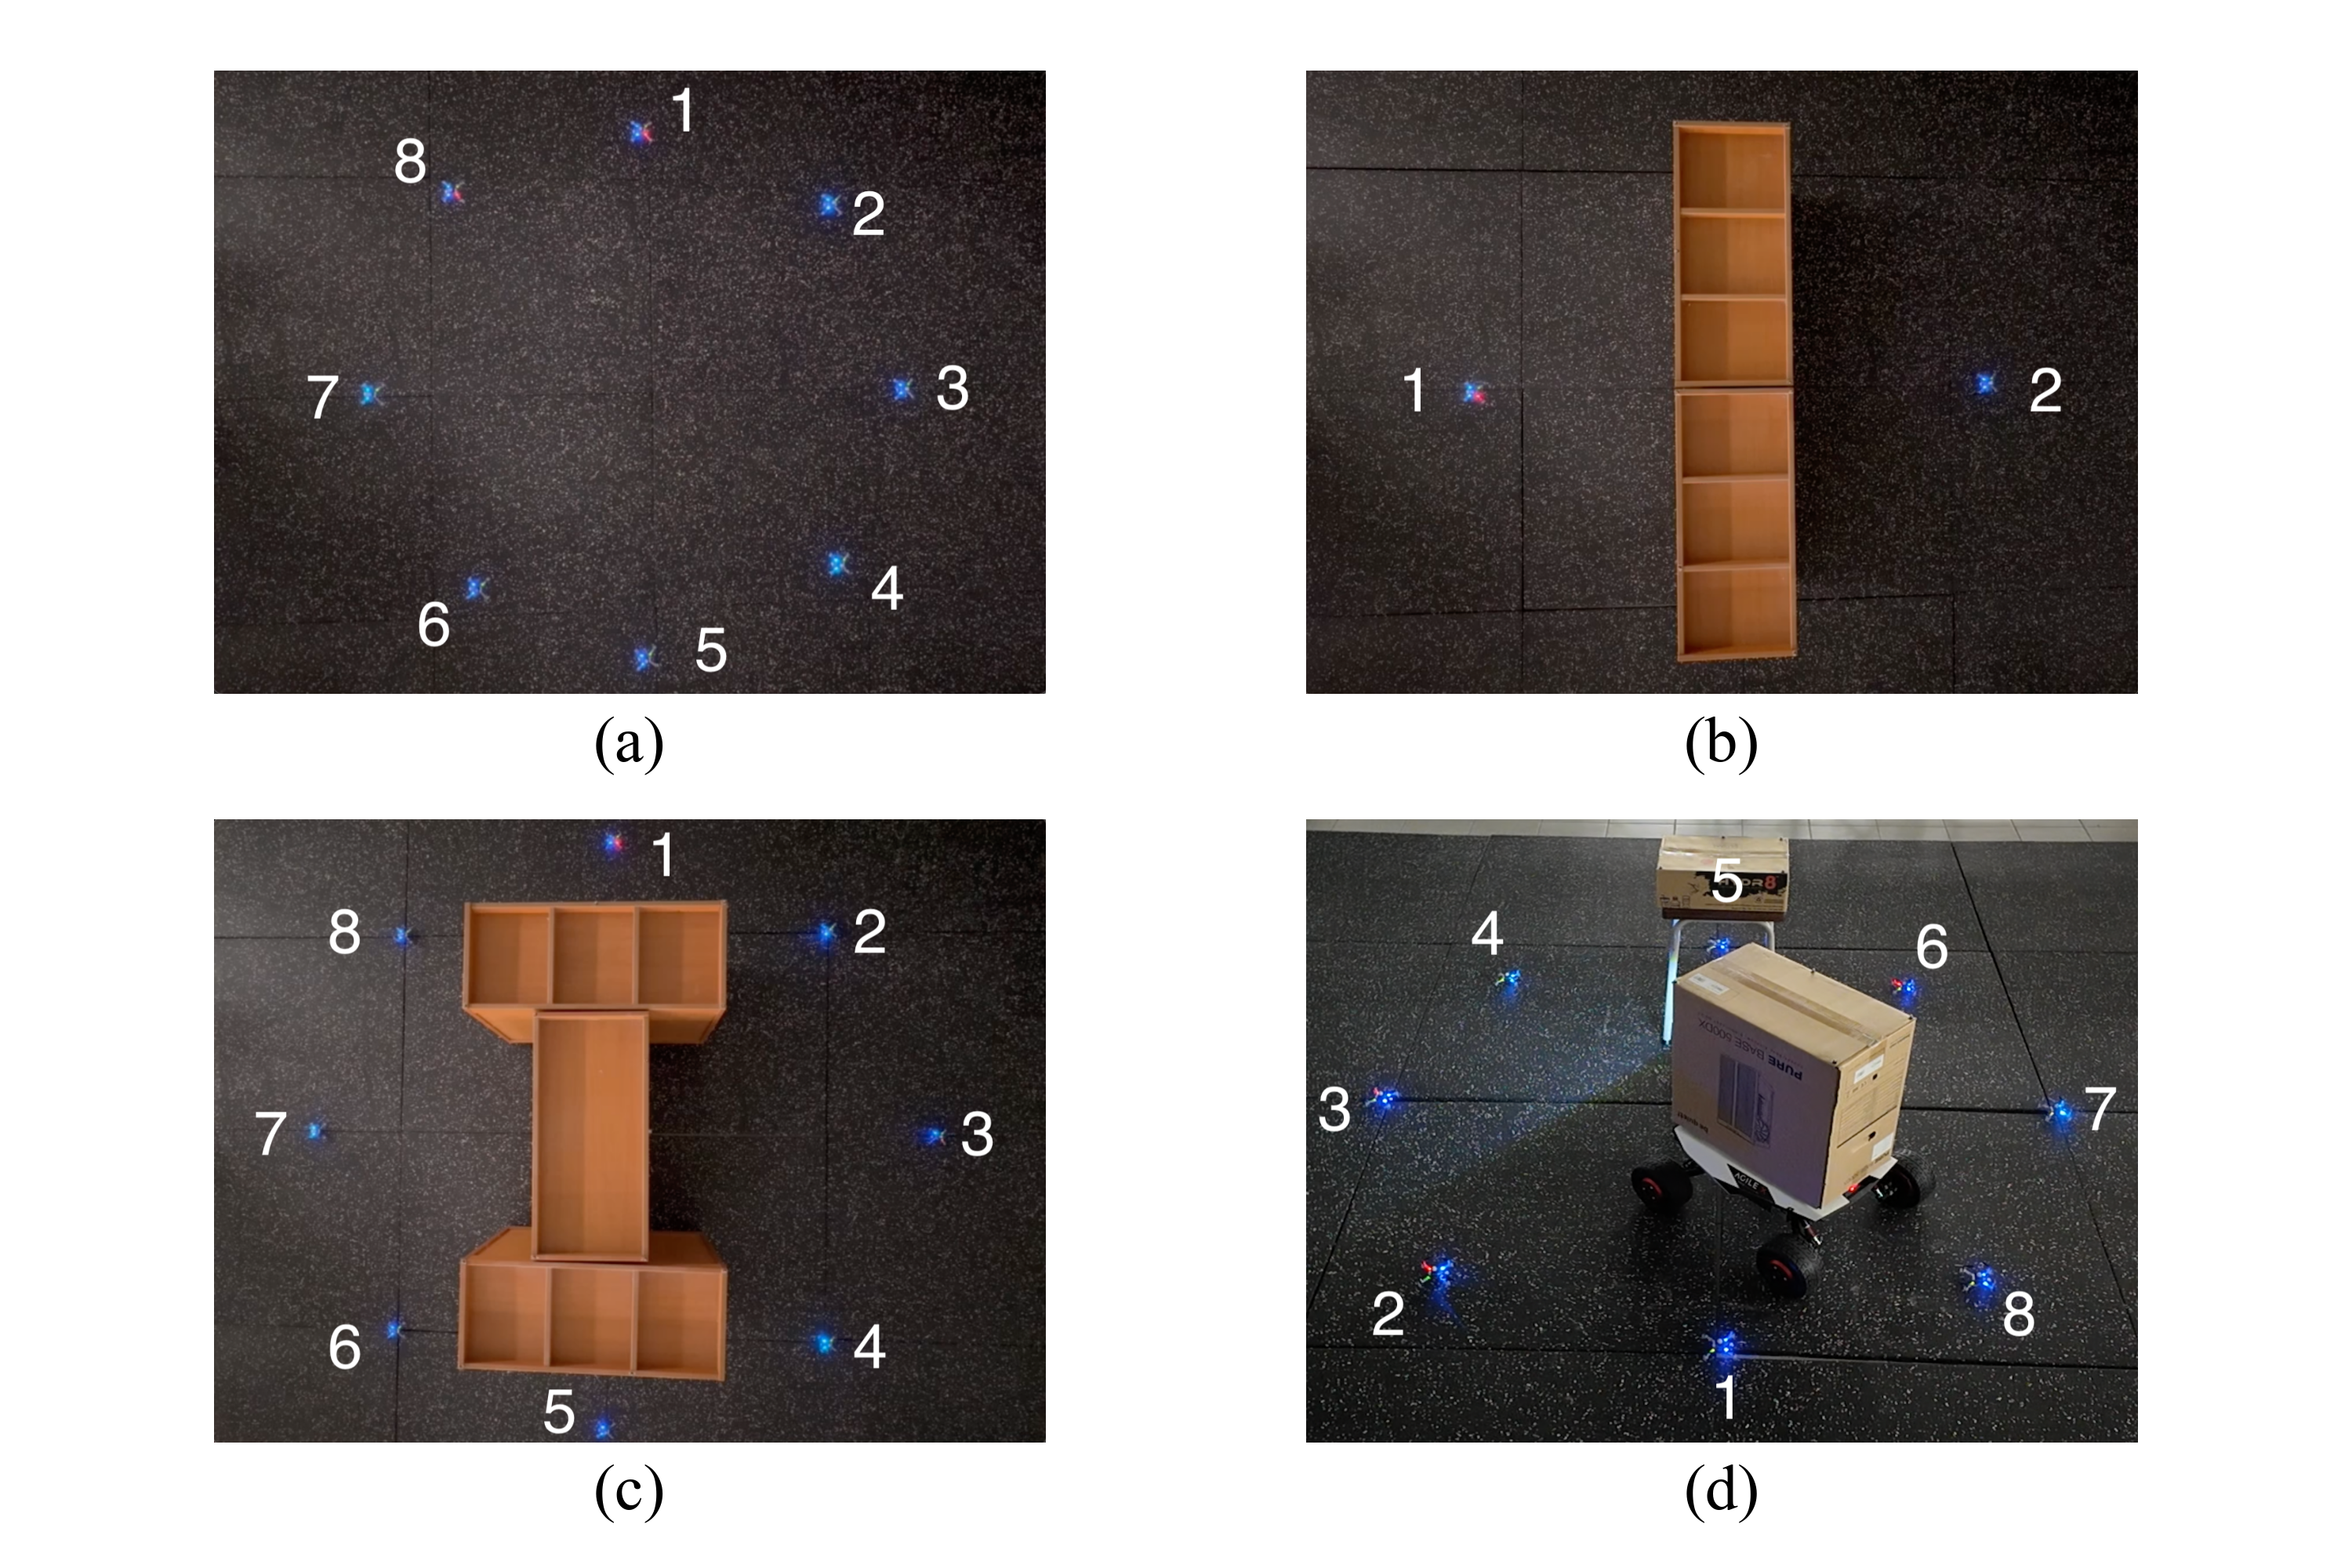
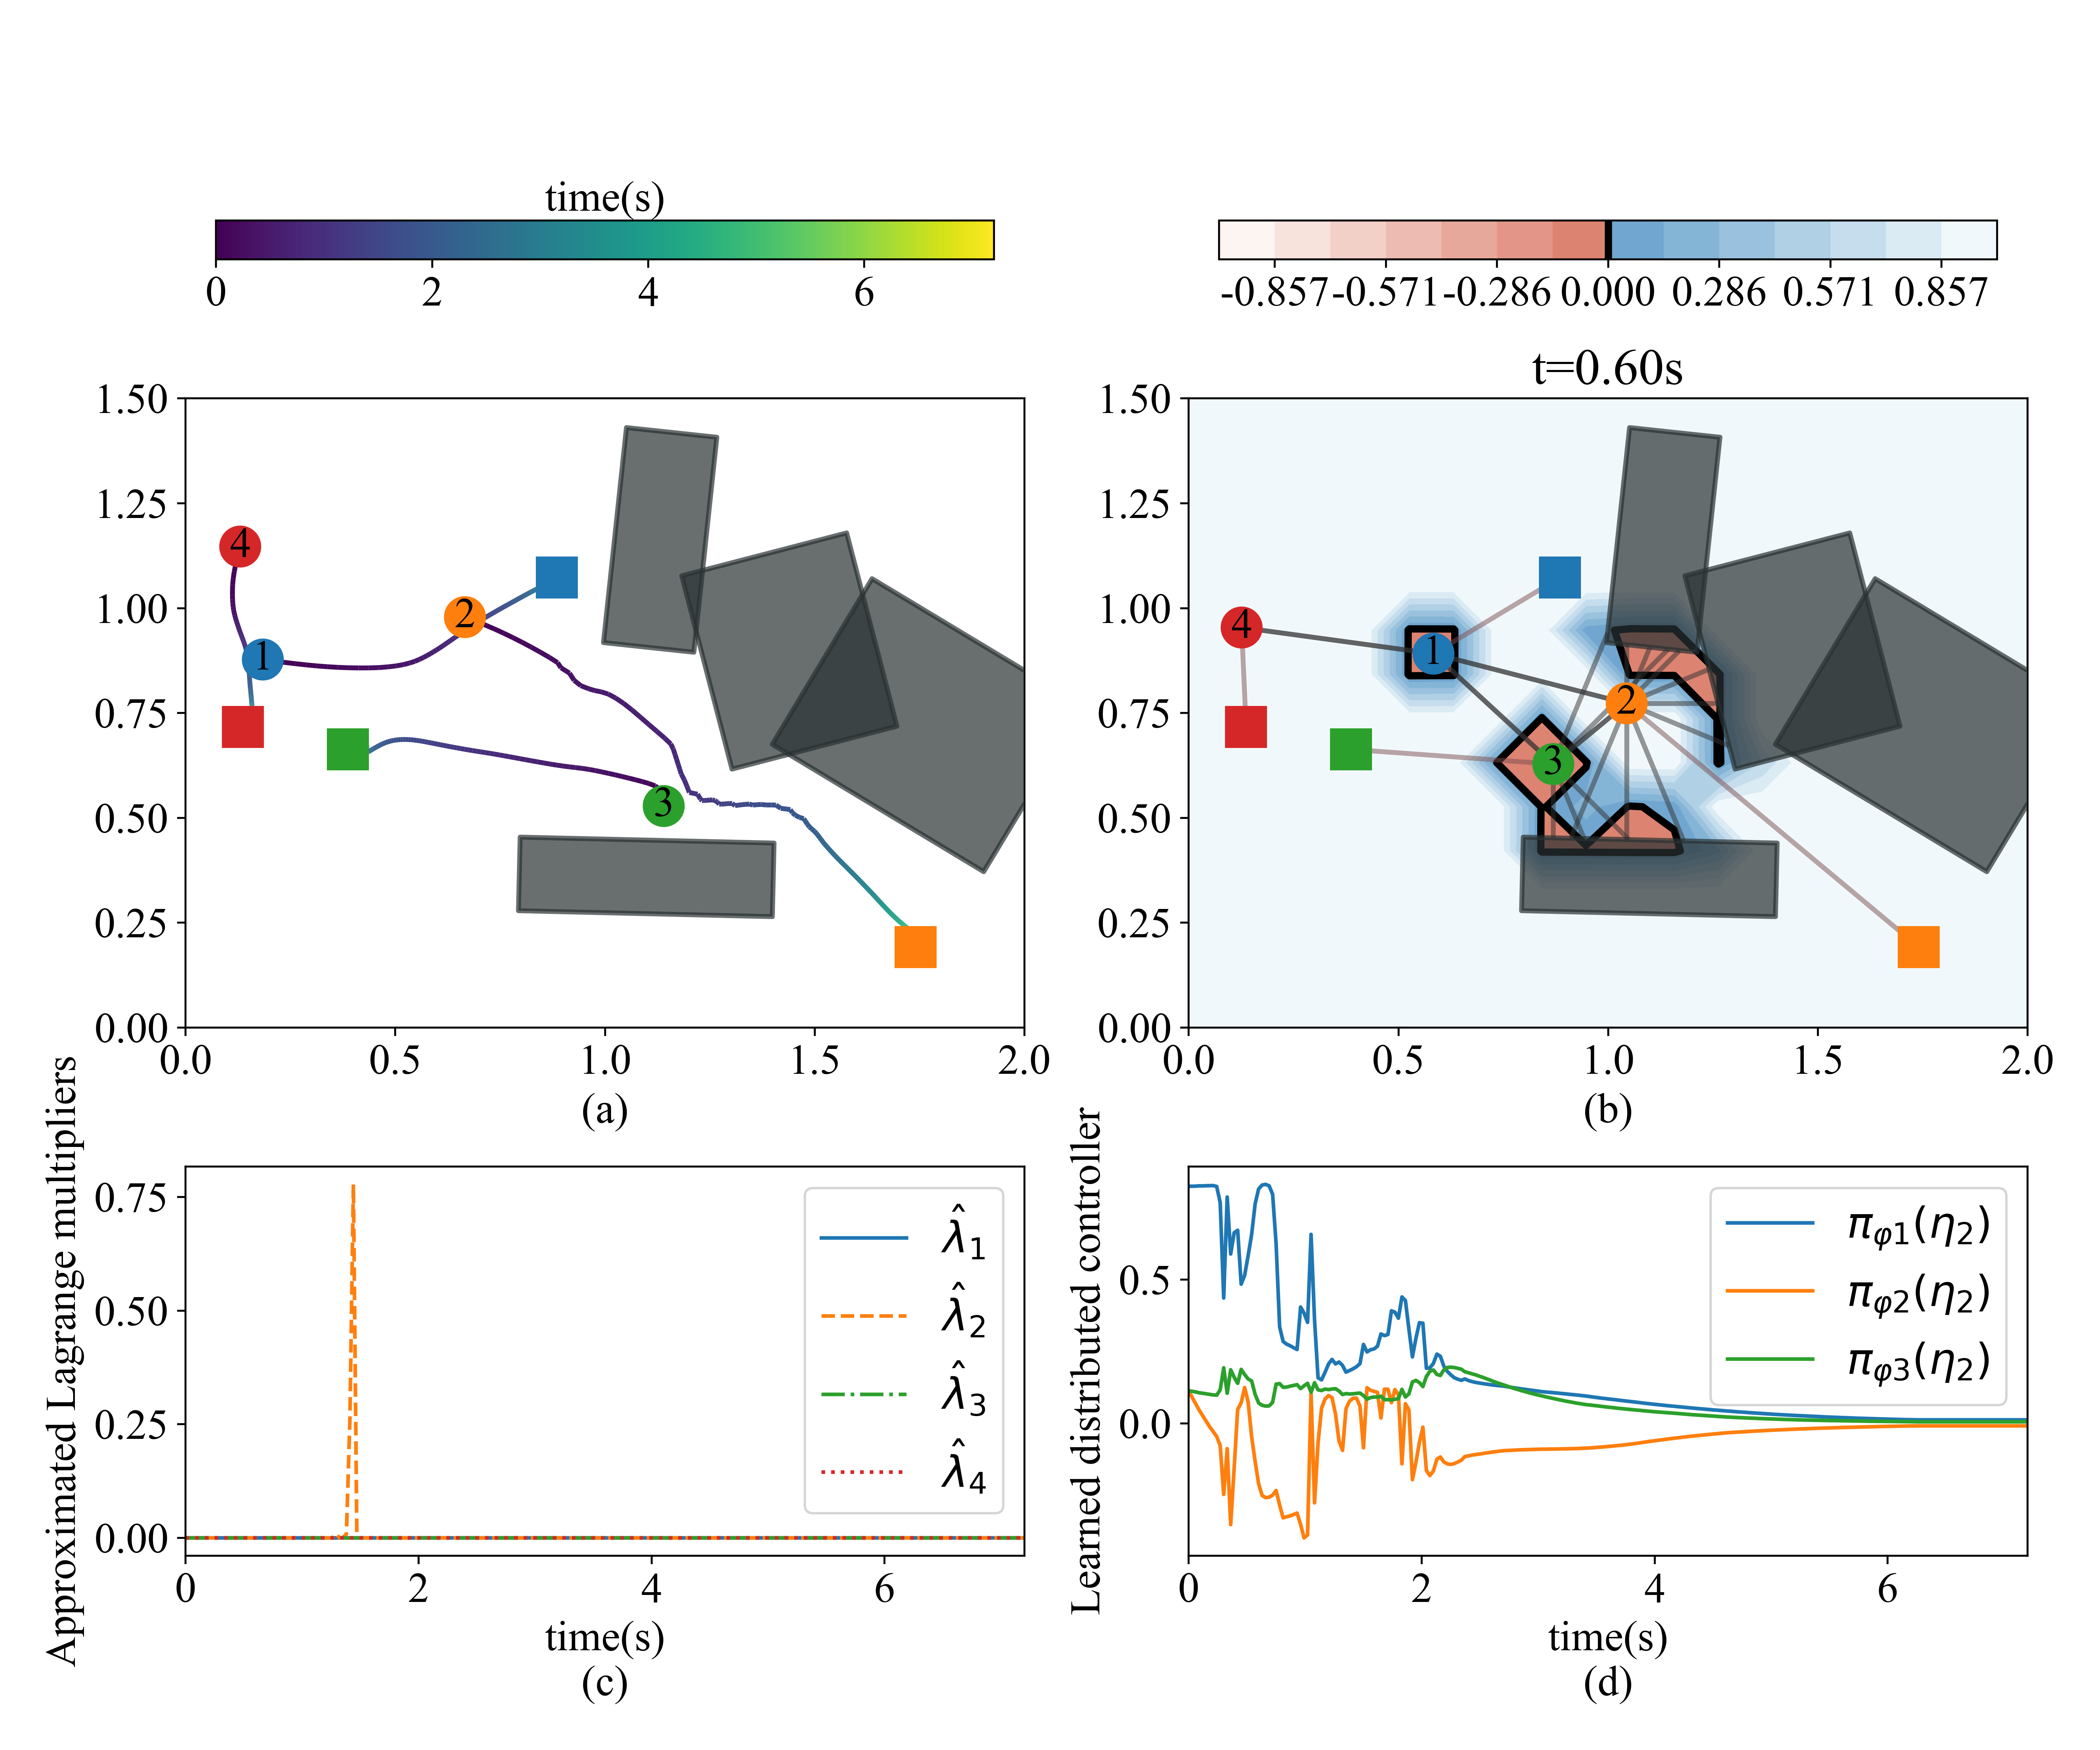
fig 5

Fig. 1 & 7. Hardware experiment setup for antipodal position-swapping task: (a) 8 Crazyflie drones without obstacle; (b) 2 Crazyflie drones with a long static obstacle; (c) 8 Crazyflie drones with large non-convex static obstacles; (d) 8 Crazyflie drones with both a static obstacle and a large dynamic obstacle mounted on a randomly moving car.


(a) 8 Crazyflie drones without obstacle

(b) 2 Crazyflie drones with a long static obstacle

(c) 8 Crazyflie drones with large non-convex static obstacles

(d) 8 Crazyflie drones with both a static obstacle and a large dynamic obstacle mounted on a randomly moving car


Simulations

HJB-GNN controller in 2D environment trained with 8 agents and tested with 128/512/1024 agents
HJB-GNN controller in 2D environment tested with 16/32/32 agents and 16/16/32 obstacles
HJB-GNN controller in 3D environment trained with 8 agents and tested with 64/128/512 agents
HJB-GNN controller in 3D environment tested with 32/64/128 agents and 16/32/64 obstacles


More simulations using HJB-GNN

fig 2 plot

Fig. 2. Adaptive trade-off between safety and goal-reaching performance for unmanned surface vessel model of [17] in cluttered, dense environment with \(2\mathrm{m} \times 1.5\mathrm{m}\). (a) Four agents safely navigate to their respective goals. Numbered circles denote initial positions of agents, squares with the same color as agents are their goals, and gray rectangles are static obstacles. (b) Learned graph CBF contour of agent 2 at \(t=0.6{\rm s}\), where the zero-level set of learned CBF identifies the safety boundaries. (c) Approximated Lagrange multipliers \(\hat{\lambda}_i, i=1,2,3,4\). (d) Learned distributed controller of agent 2. Detailed simulation setup is illustrated in Appendix


fig 1

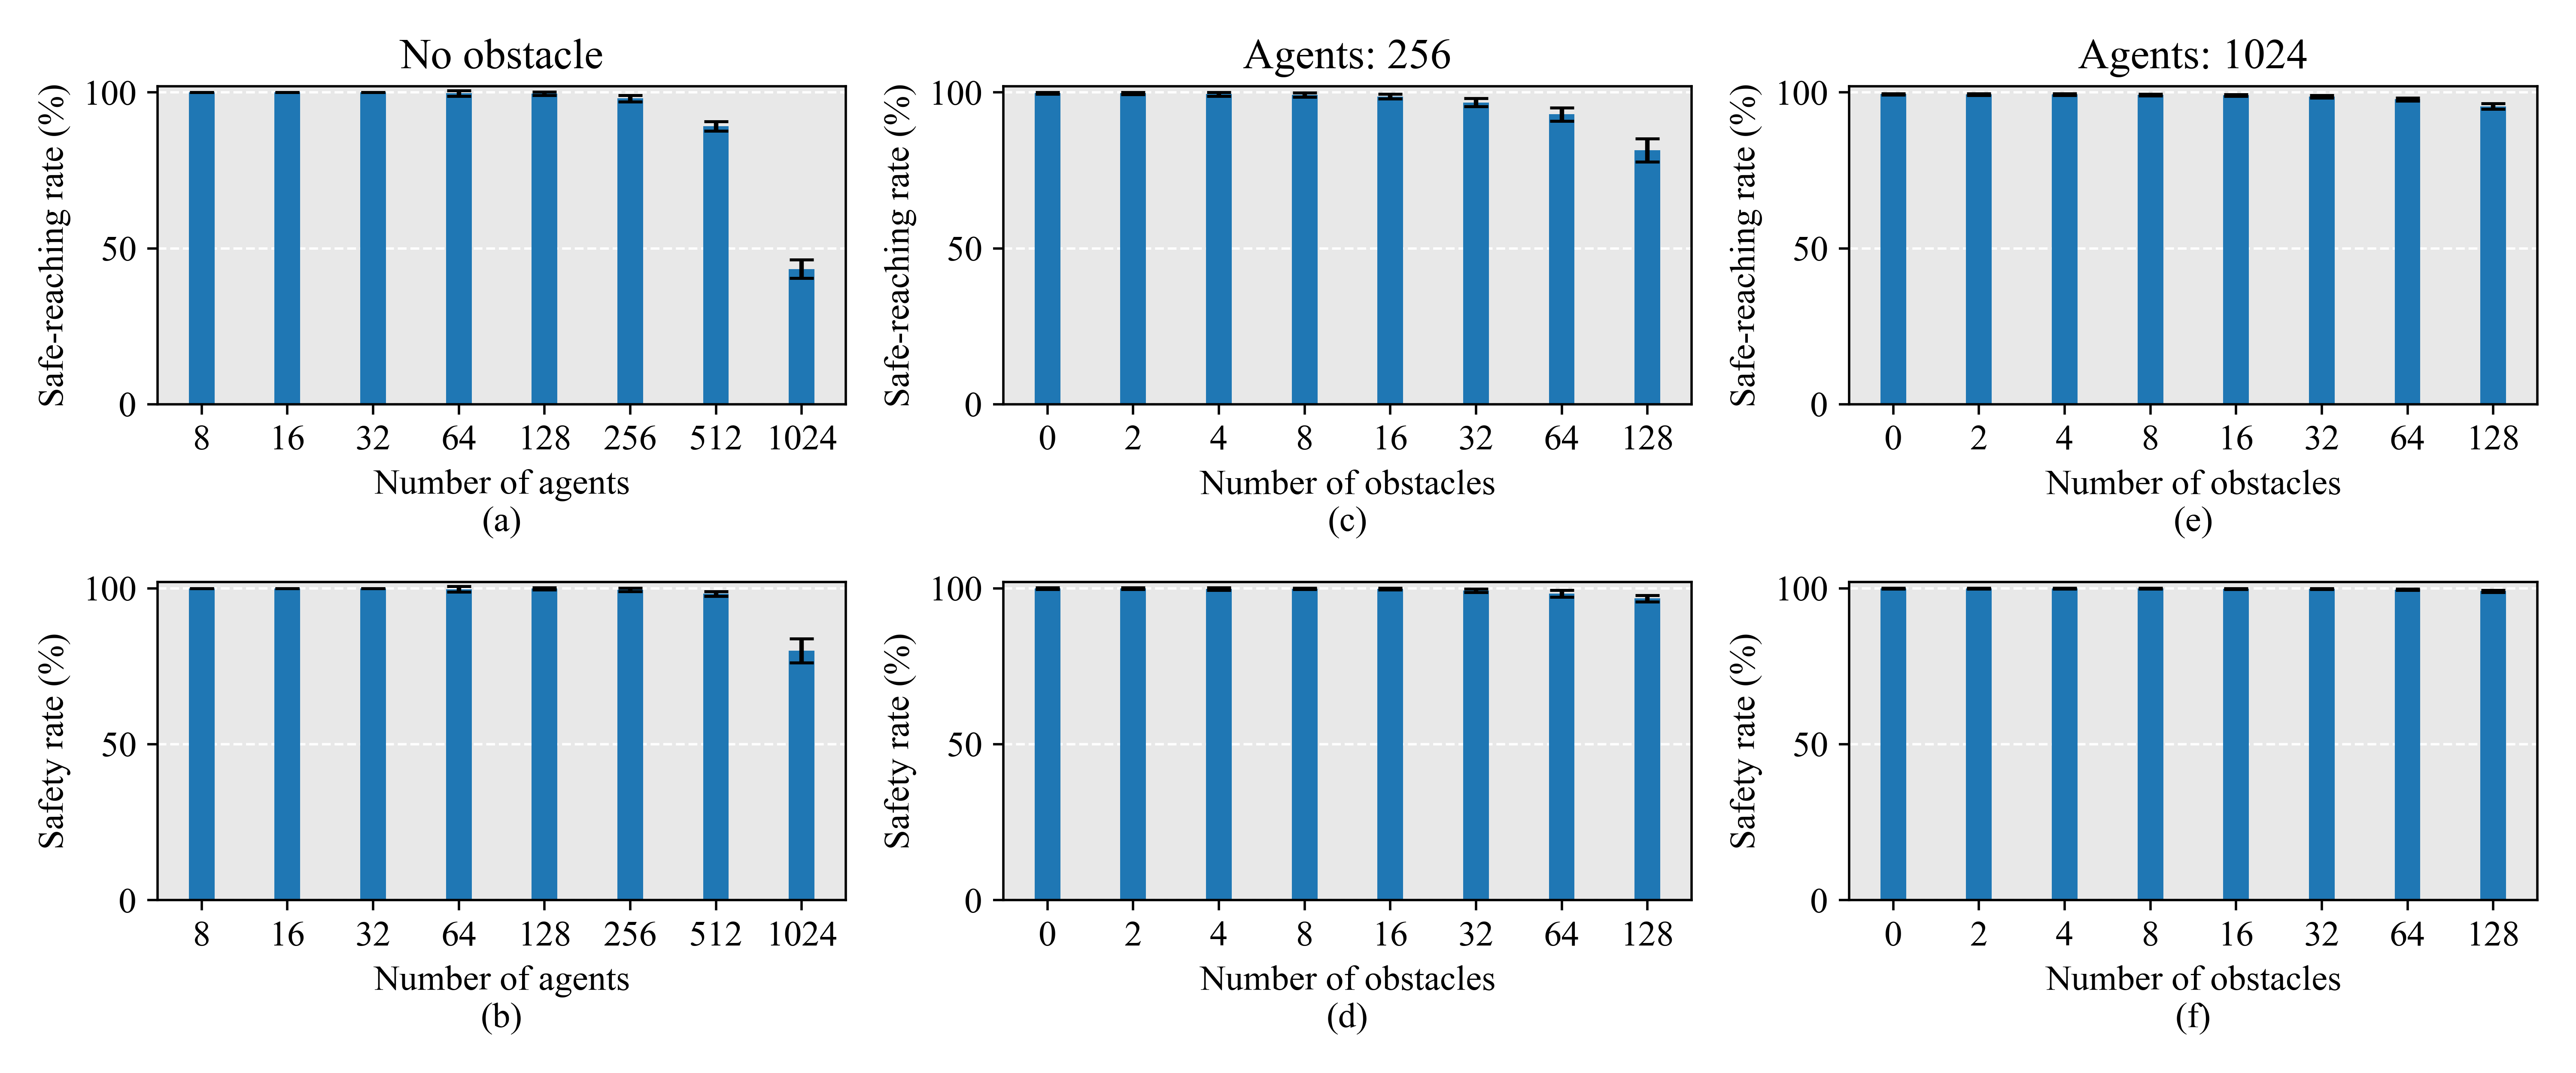
Fig. 8. Safe-reaching rates ((a), (c), (e)) and safety rates ((b), (d), (f)) for 2D unmanned surface vessel under fixed area width. (a)-(b): no obstacle with increasing numbers of agents, (c)-(d): 256 agents with increasing numbers of obstacles, and (e)-(f): 1024 agents with increasing numbers of obstacles.


Comparative simulations between HJB-GNN and QP-GCBF+

fig 6 plot

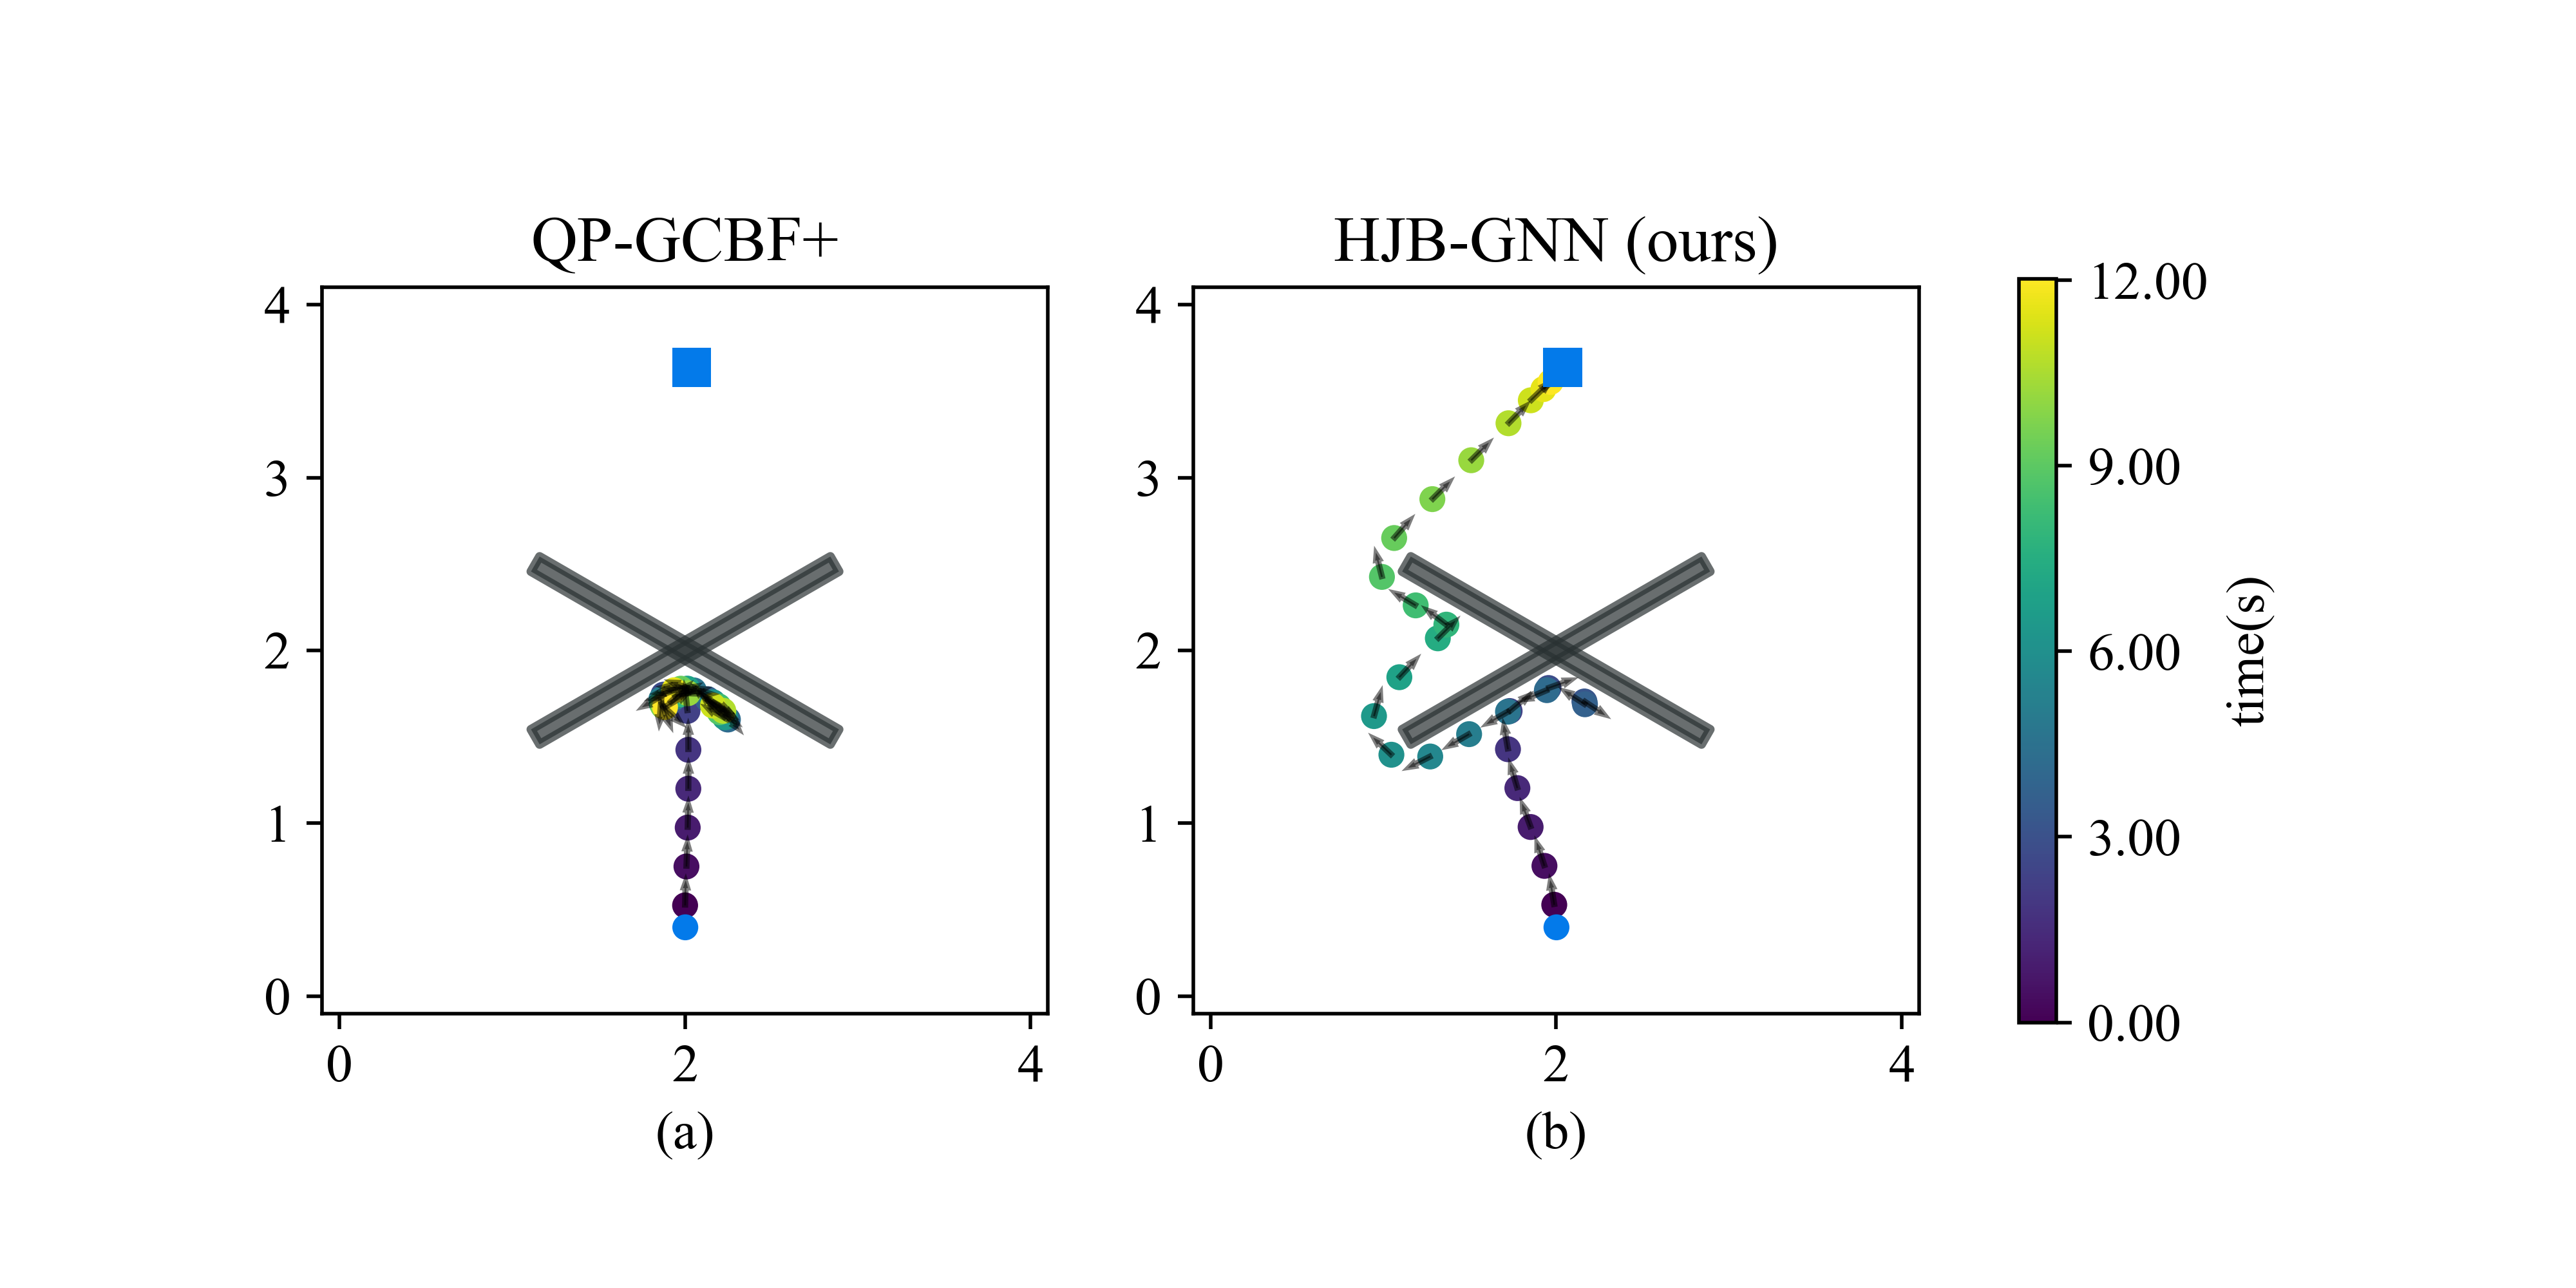
Fig. 3. Comparison between QP-GCBF+ of [35] in (a) and our HJB-GNN in (b). An agent (a gradient-colored circle) aims to reach the goal (blue square) while avoiding static obstacles (gray rectangles) within a \(4{\rm m}\times4{\rm m}\) region. Black arrow indicates the velocity direction of agent. The QP-GCBF+ has deadlock near obstacles, and the HJB-GNN achieves goal-reaching without collision.


fig 7

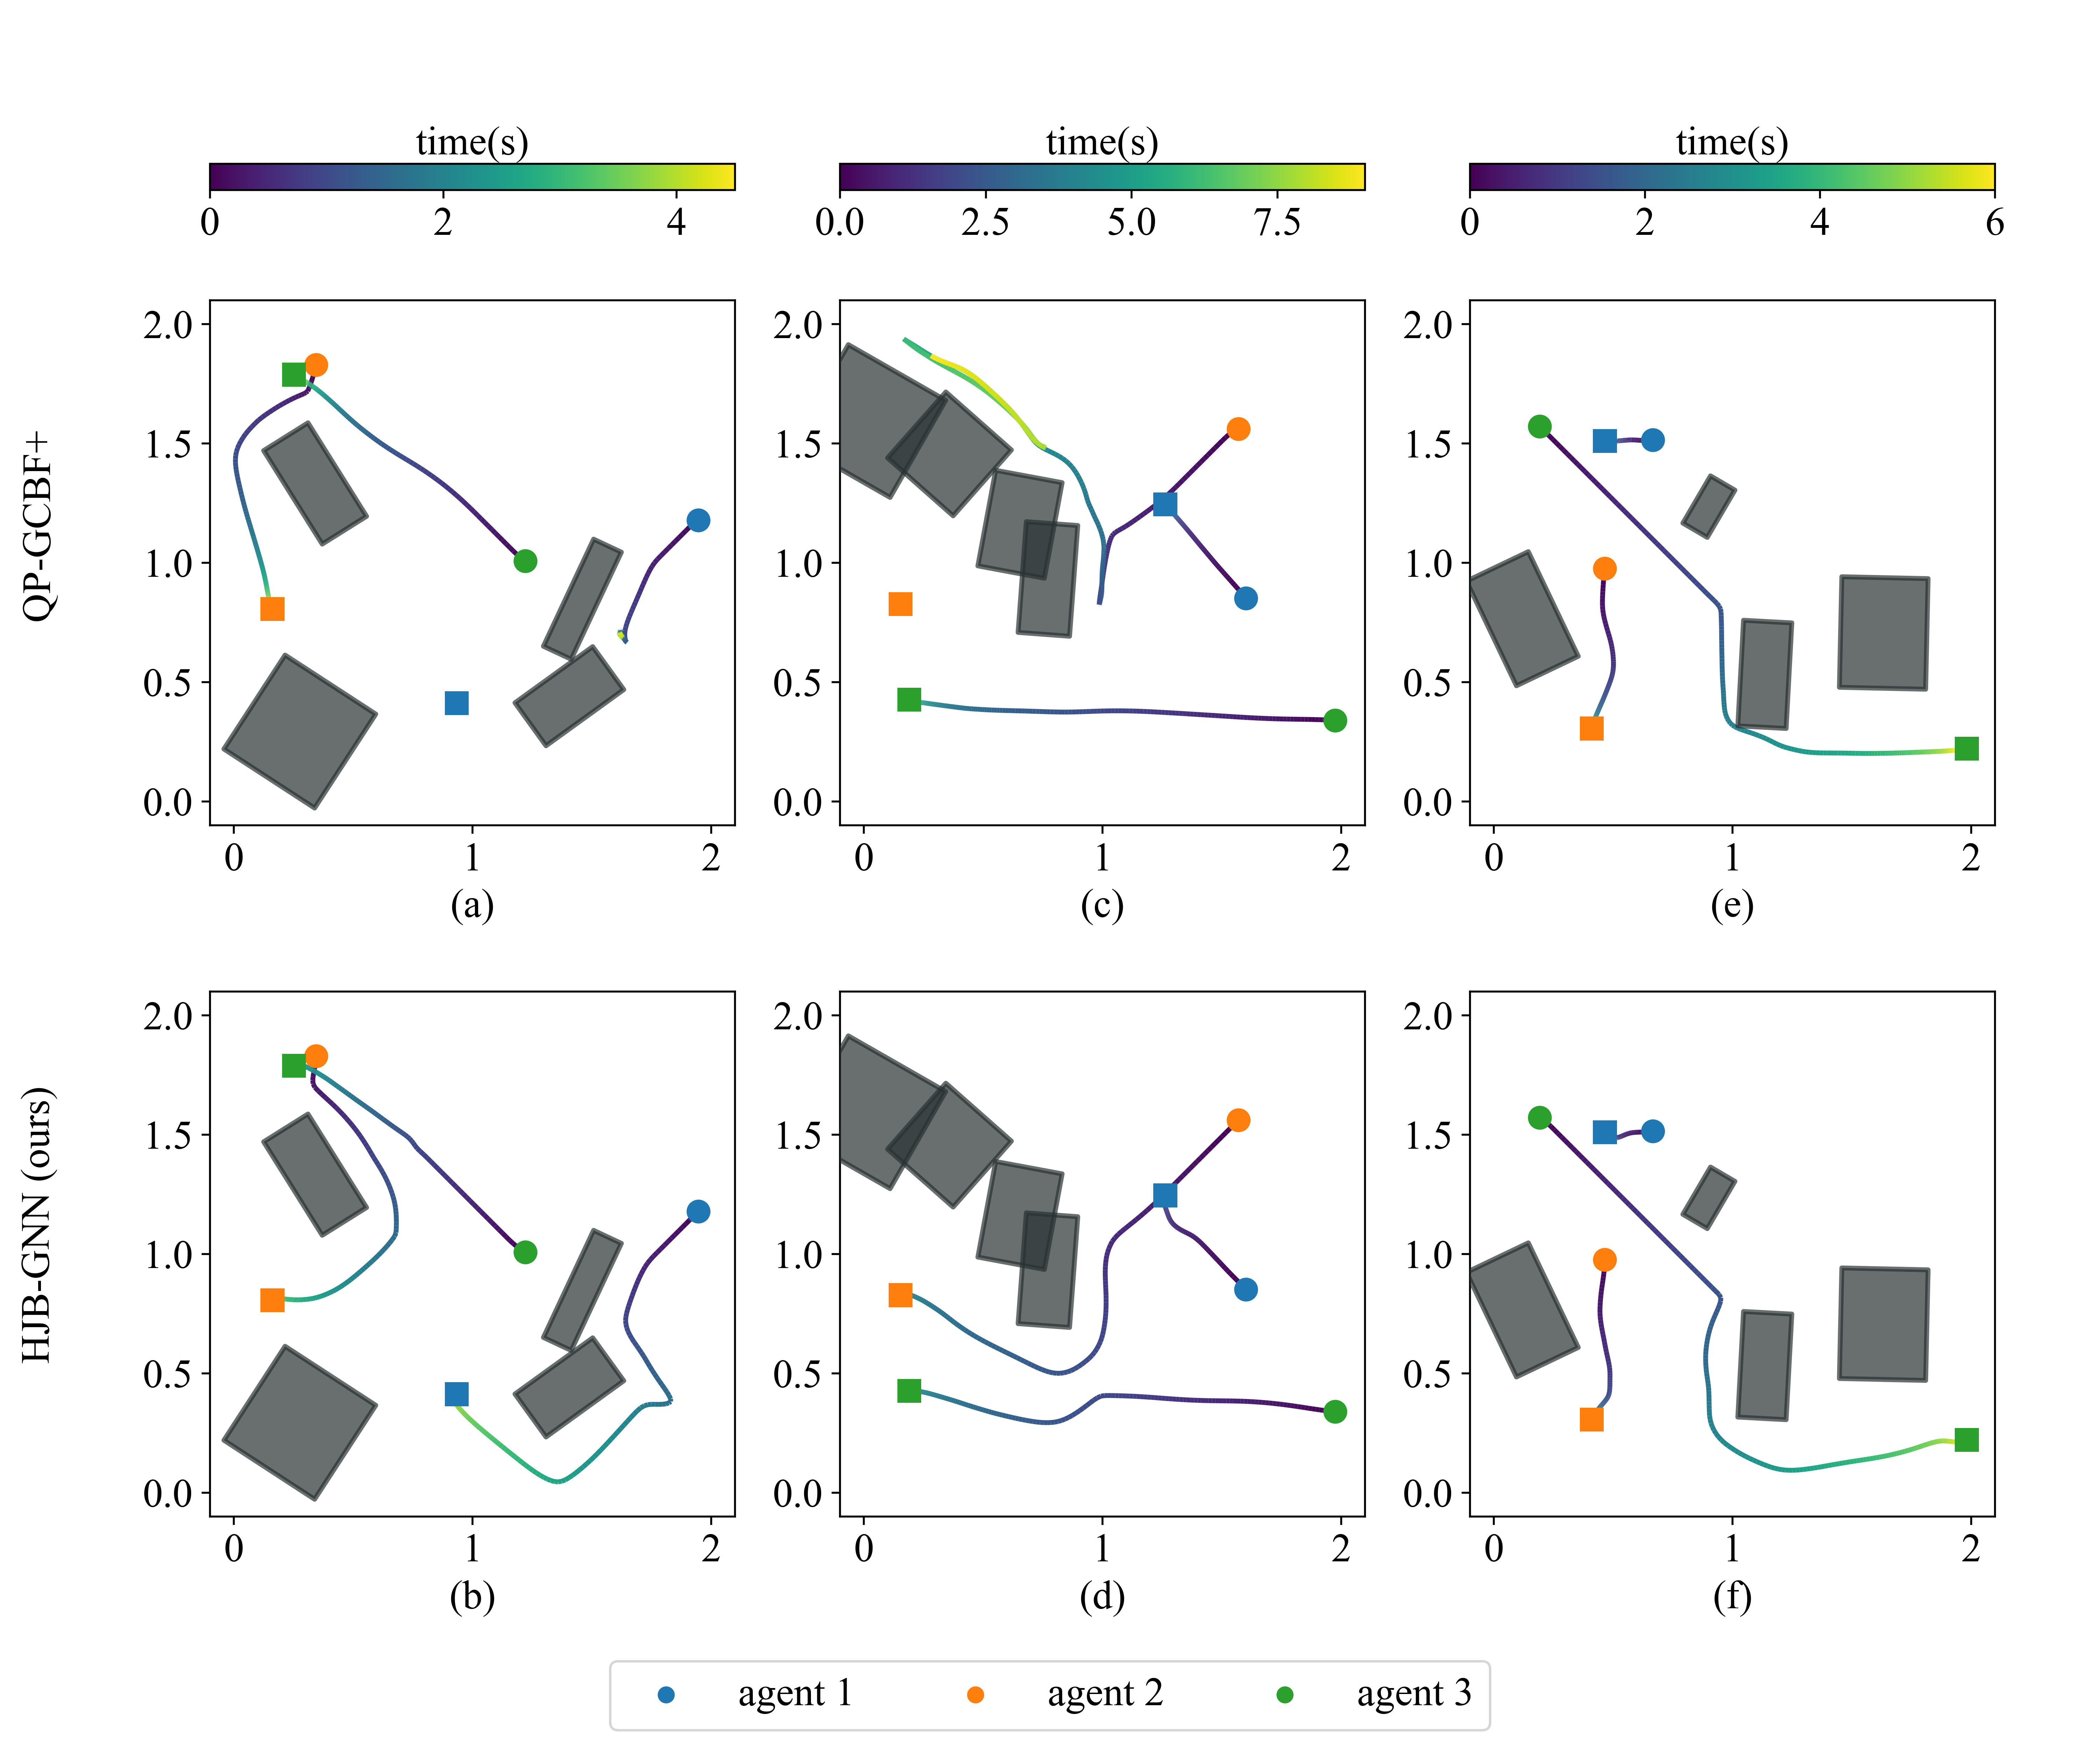
Fig. 4. Comparisons between the QP-GCBF+ method ((a), (c), and (e)) in [35] and our HJB-GNN approach ((b), (d), and (f)) under three cases with four agents (circles indicating their initial positions) and four static obstacles (gray rectangles) in a \(2{\rm m}\times2{\rm m}\) region. Agent 1 in (a) and agent 2 in (c) experience deadlock, and agent 3 in (e) collides with an obstacle. All agents safely reach their respective goals (squares with the same colors as agents) in (b), (d), and (f).


fig 3

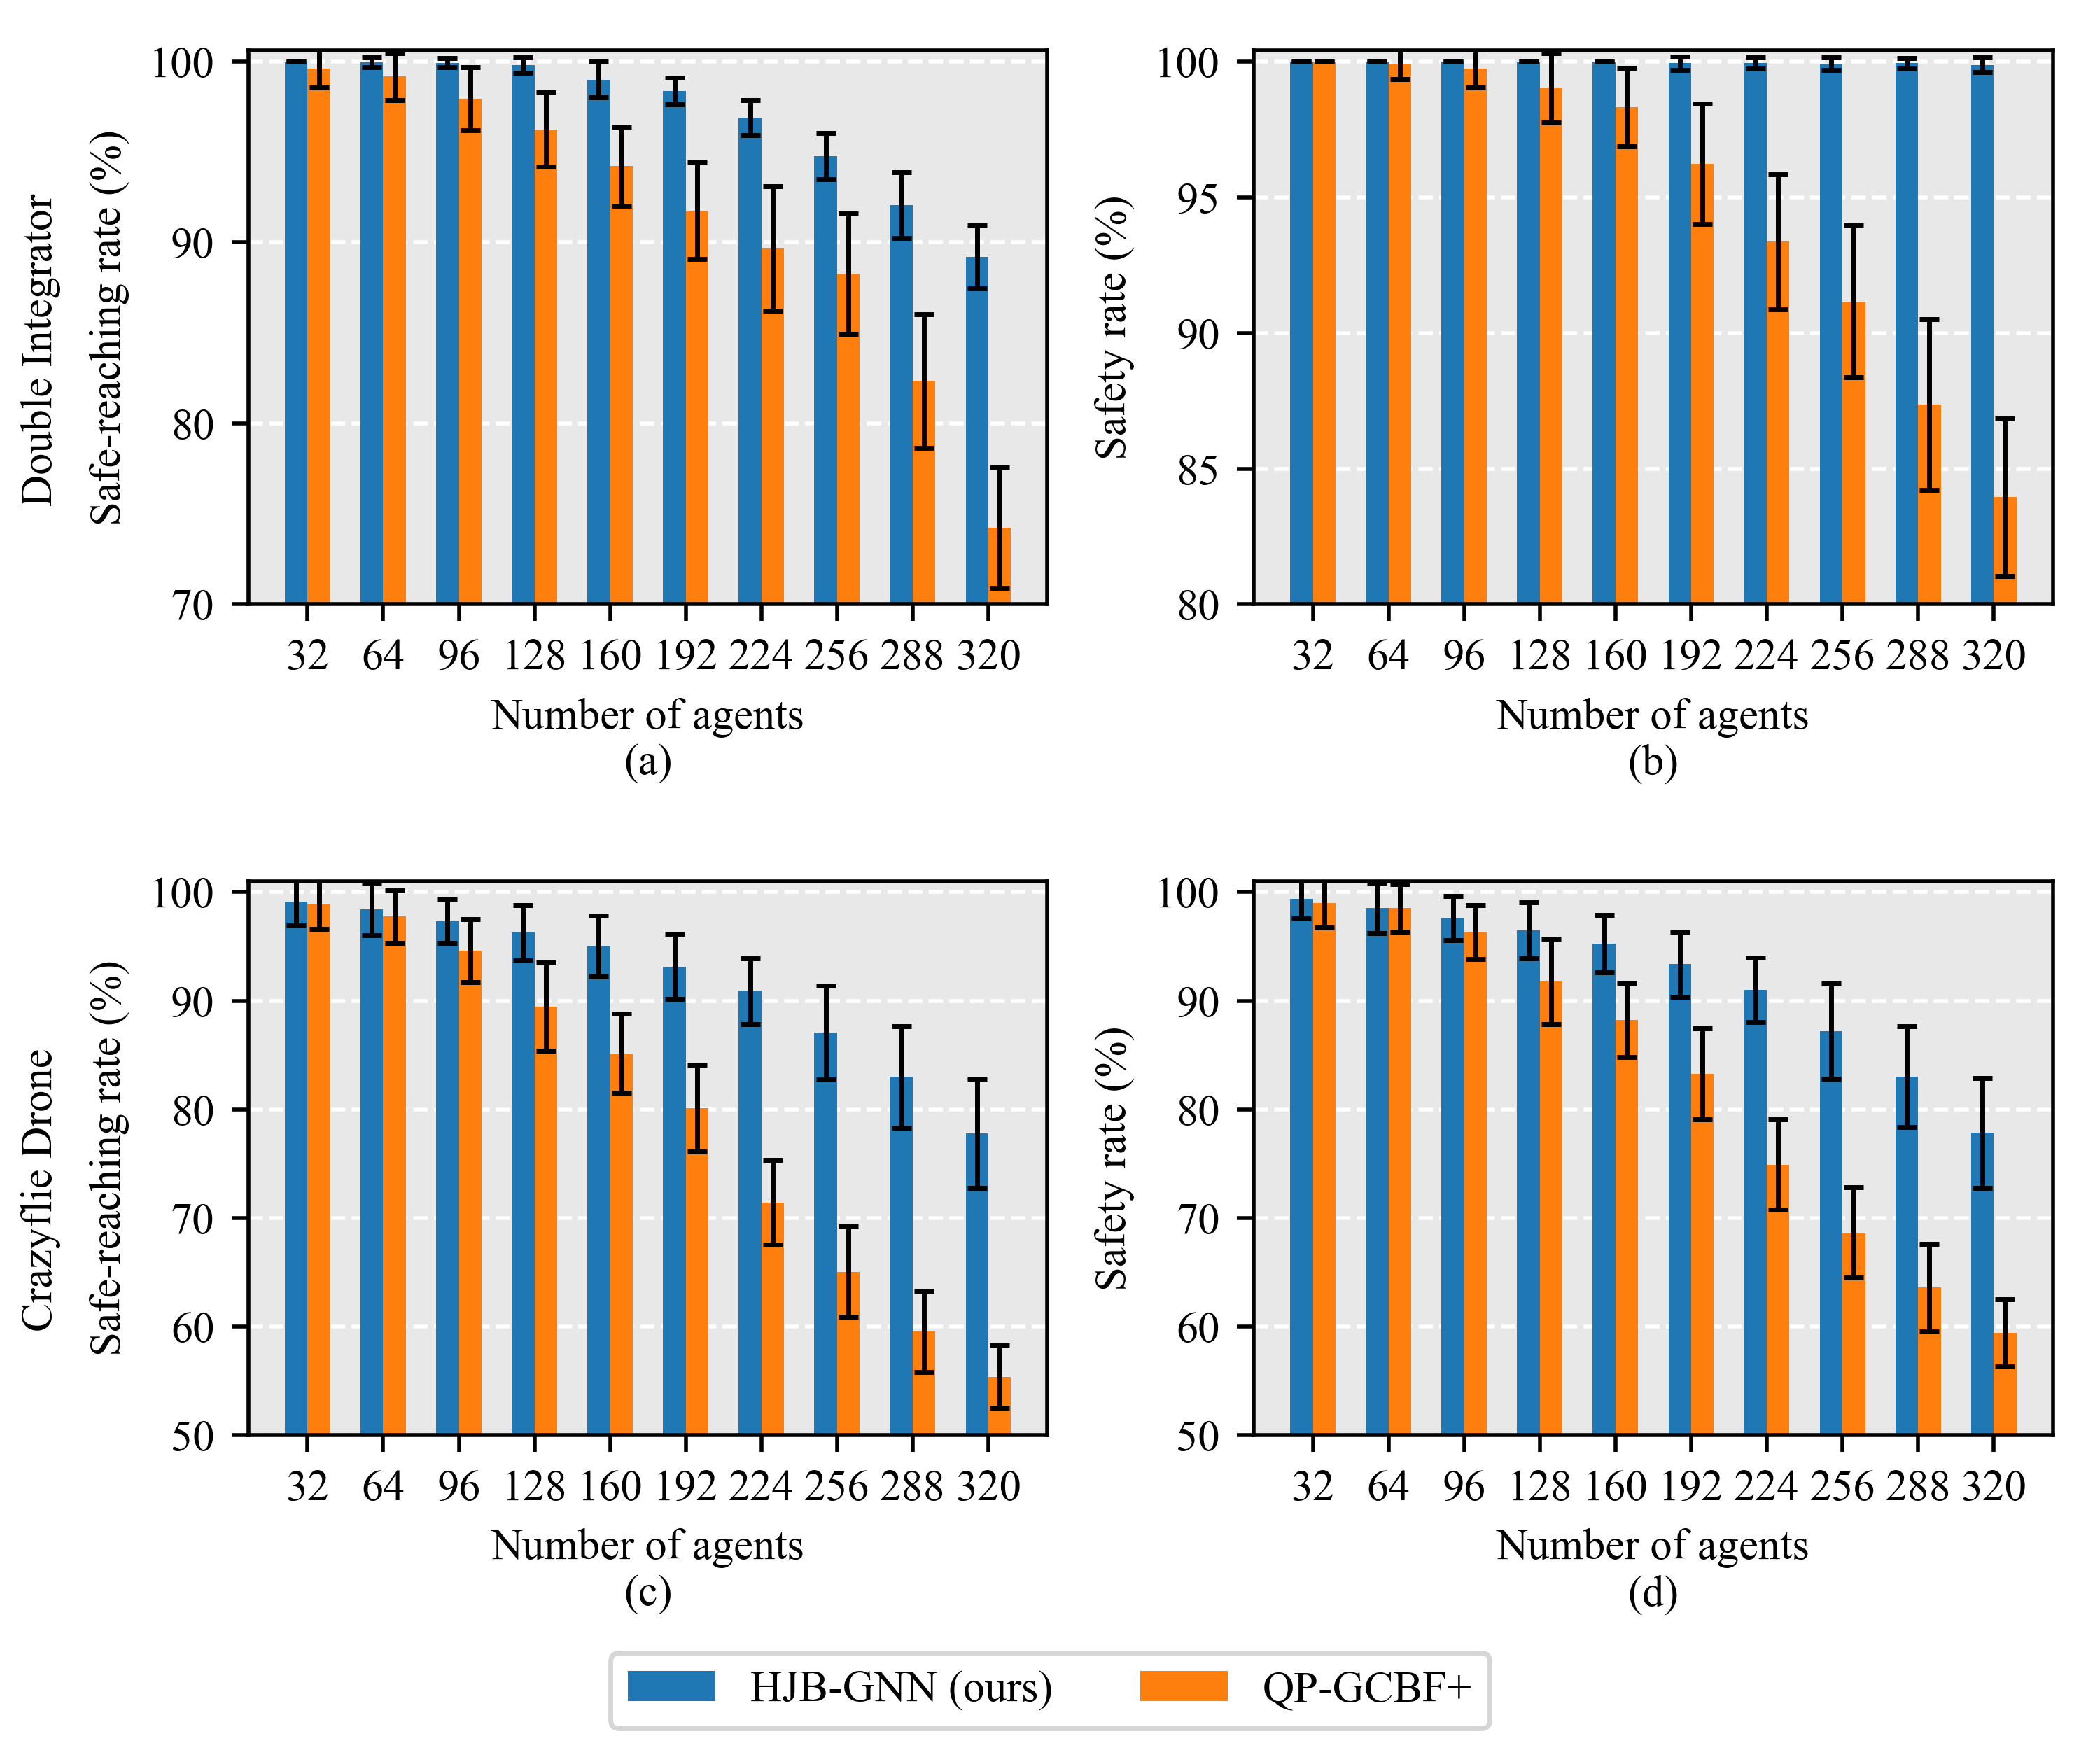
Fig. 9. Safe-reaching rates and safety rates for increasing numbers of agents and no obstacle under fixed area width. (a)-(b): 2D double integrator, and (c)-(d): 3D Crazyflie drone.

fig 4

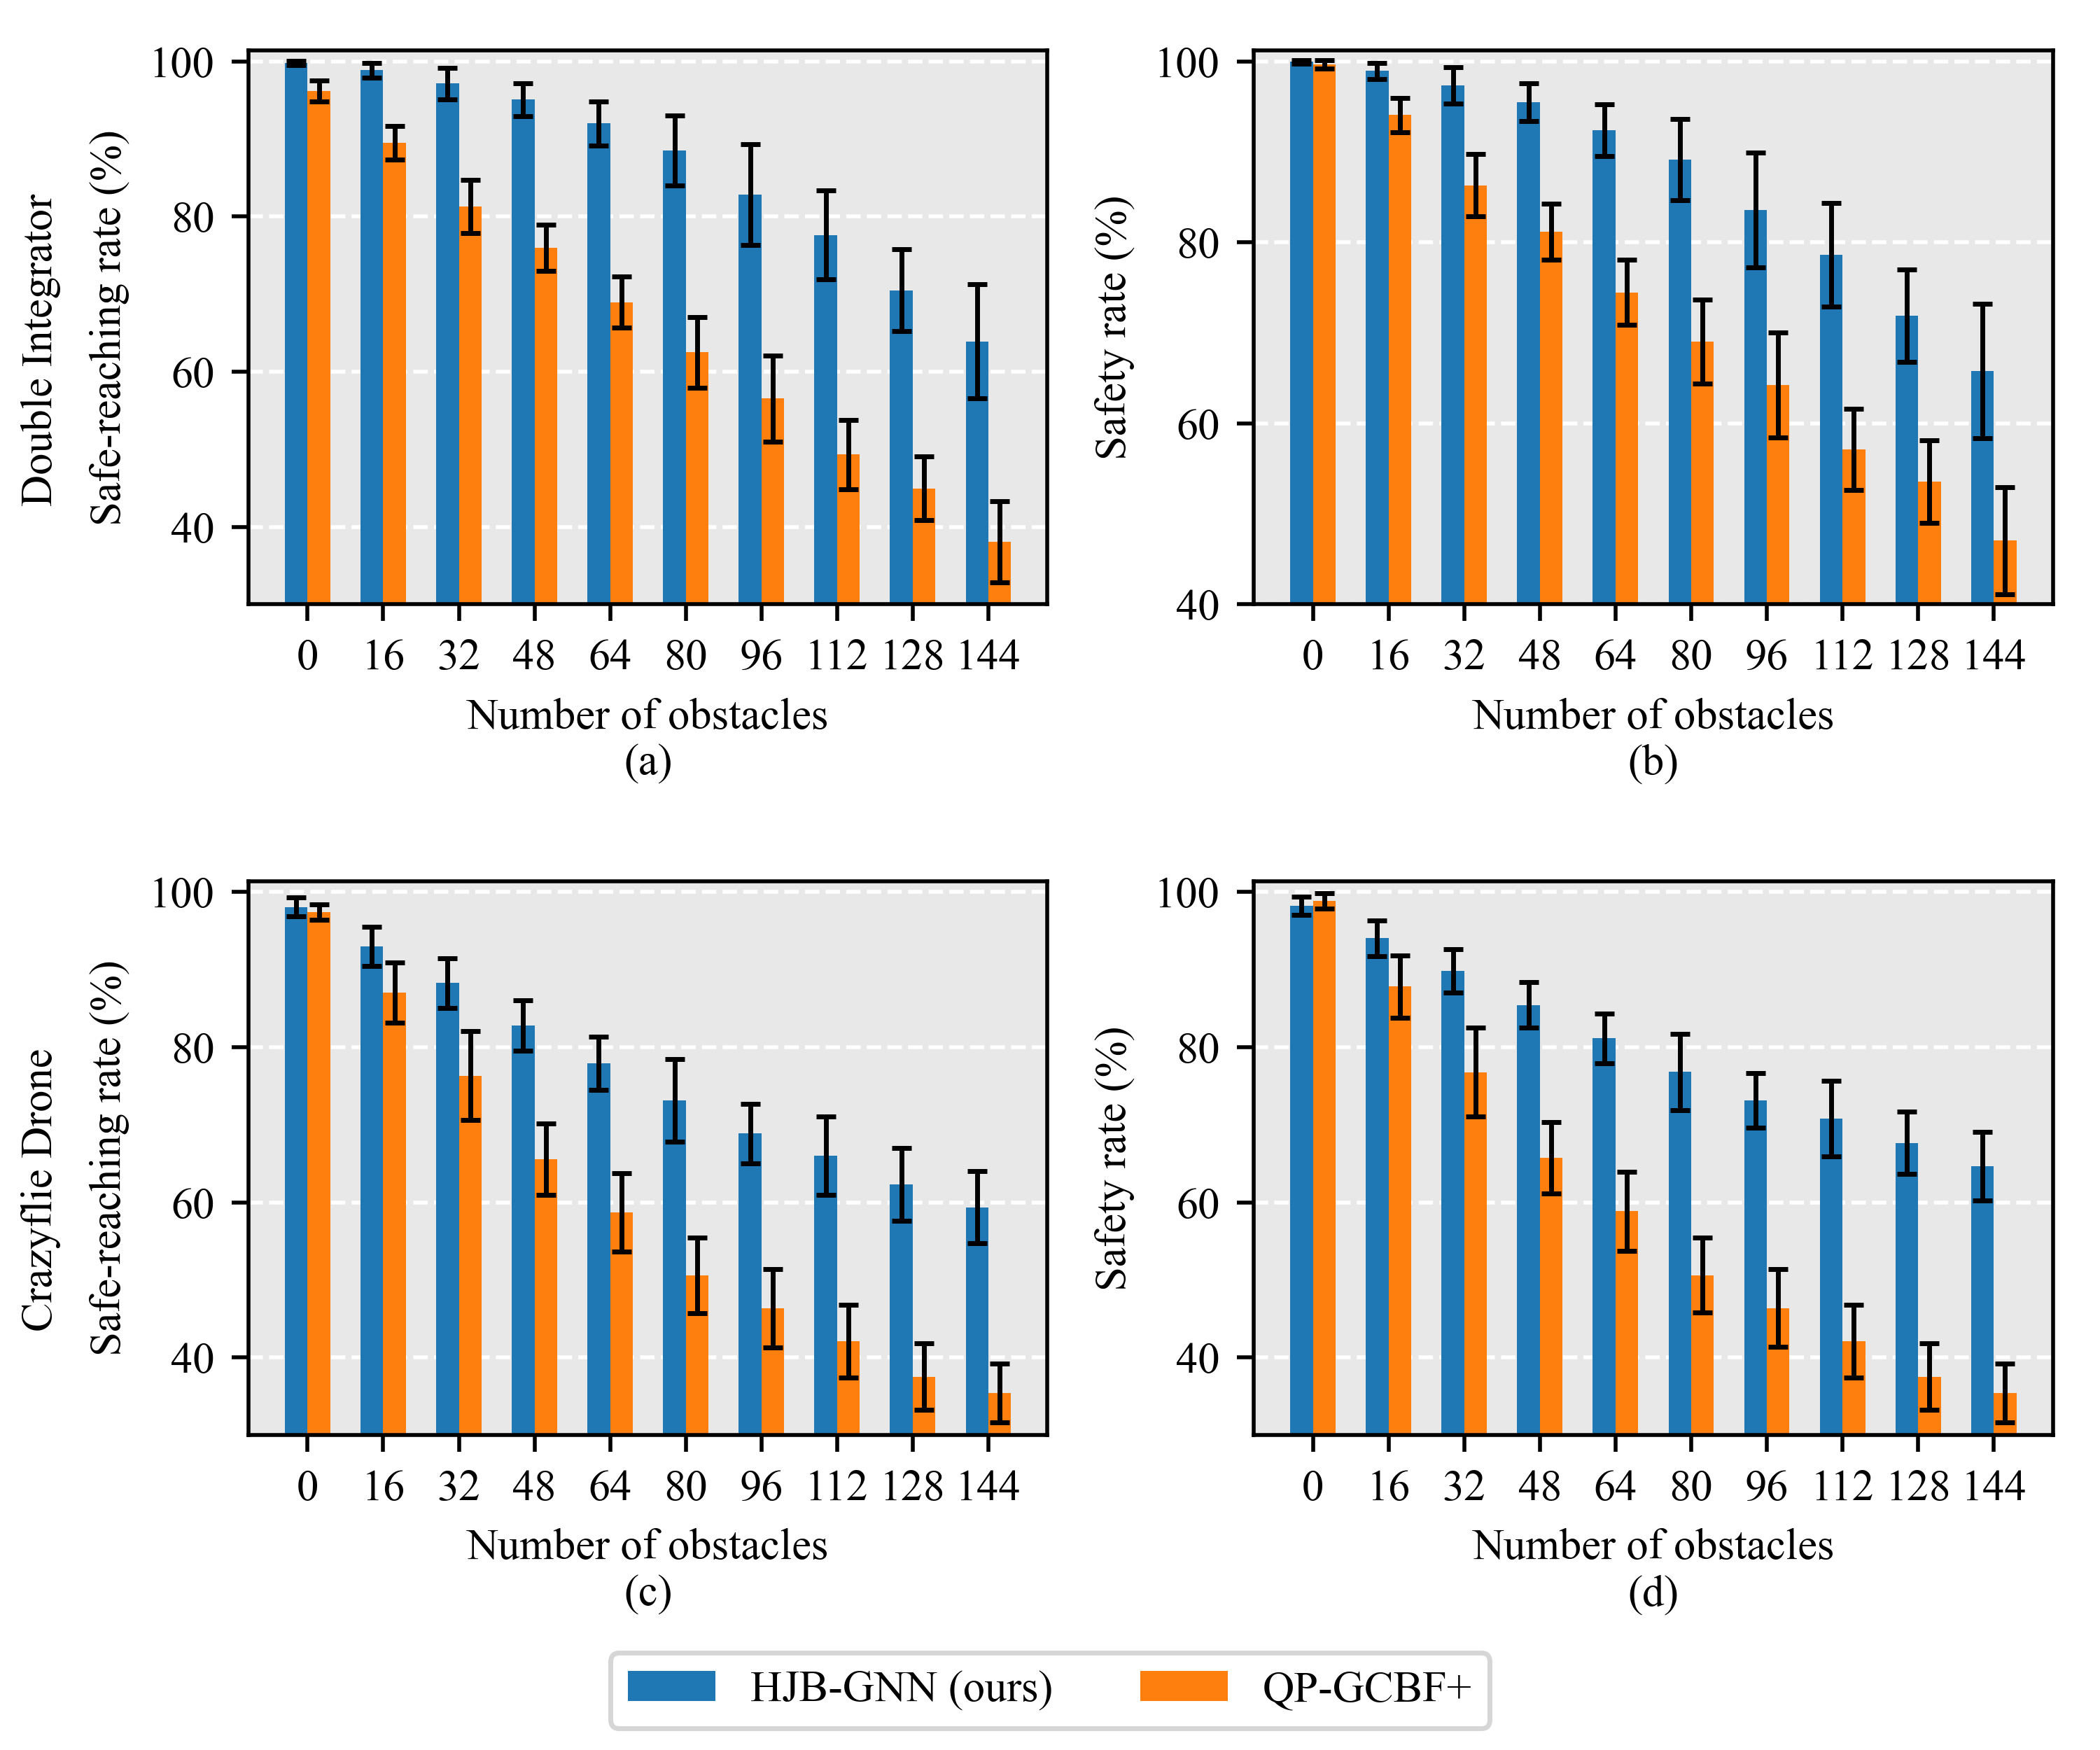
Fig. 5. Safe-reaching rates and safety rates for increasing numbers of obstacles and 256 agents under fixed area width. (a)-(b): 2D double integrator, and (c)-(d): 3D Crazyflie drone.

fig 5

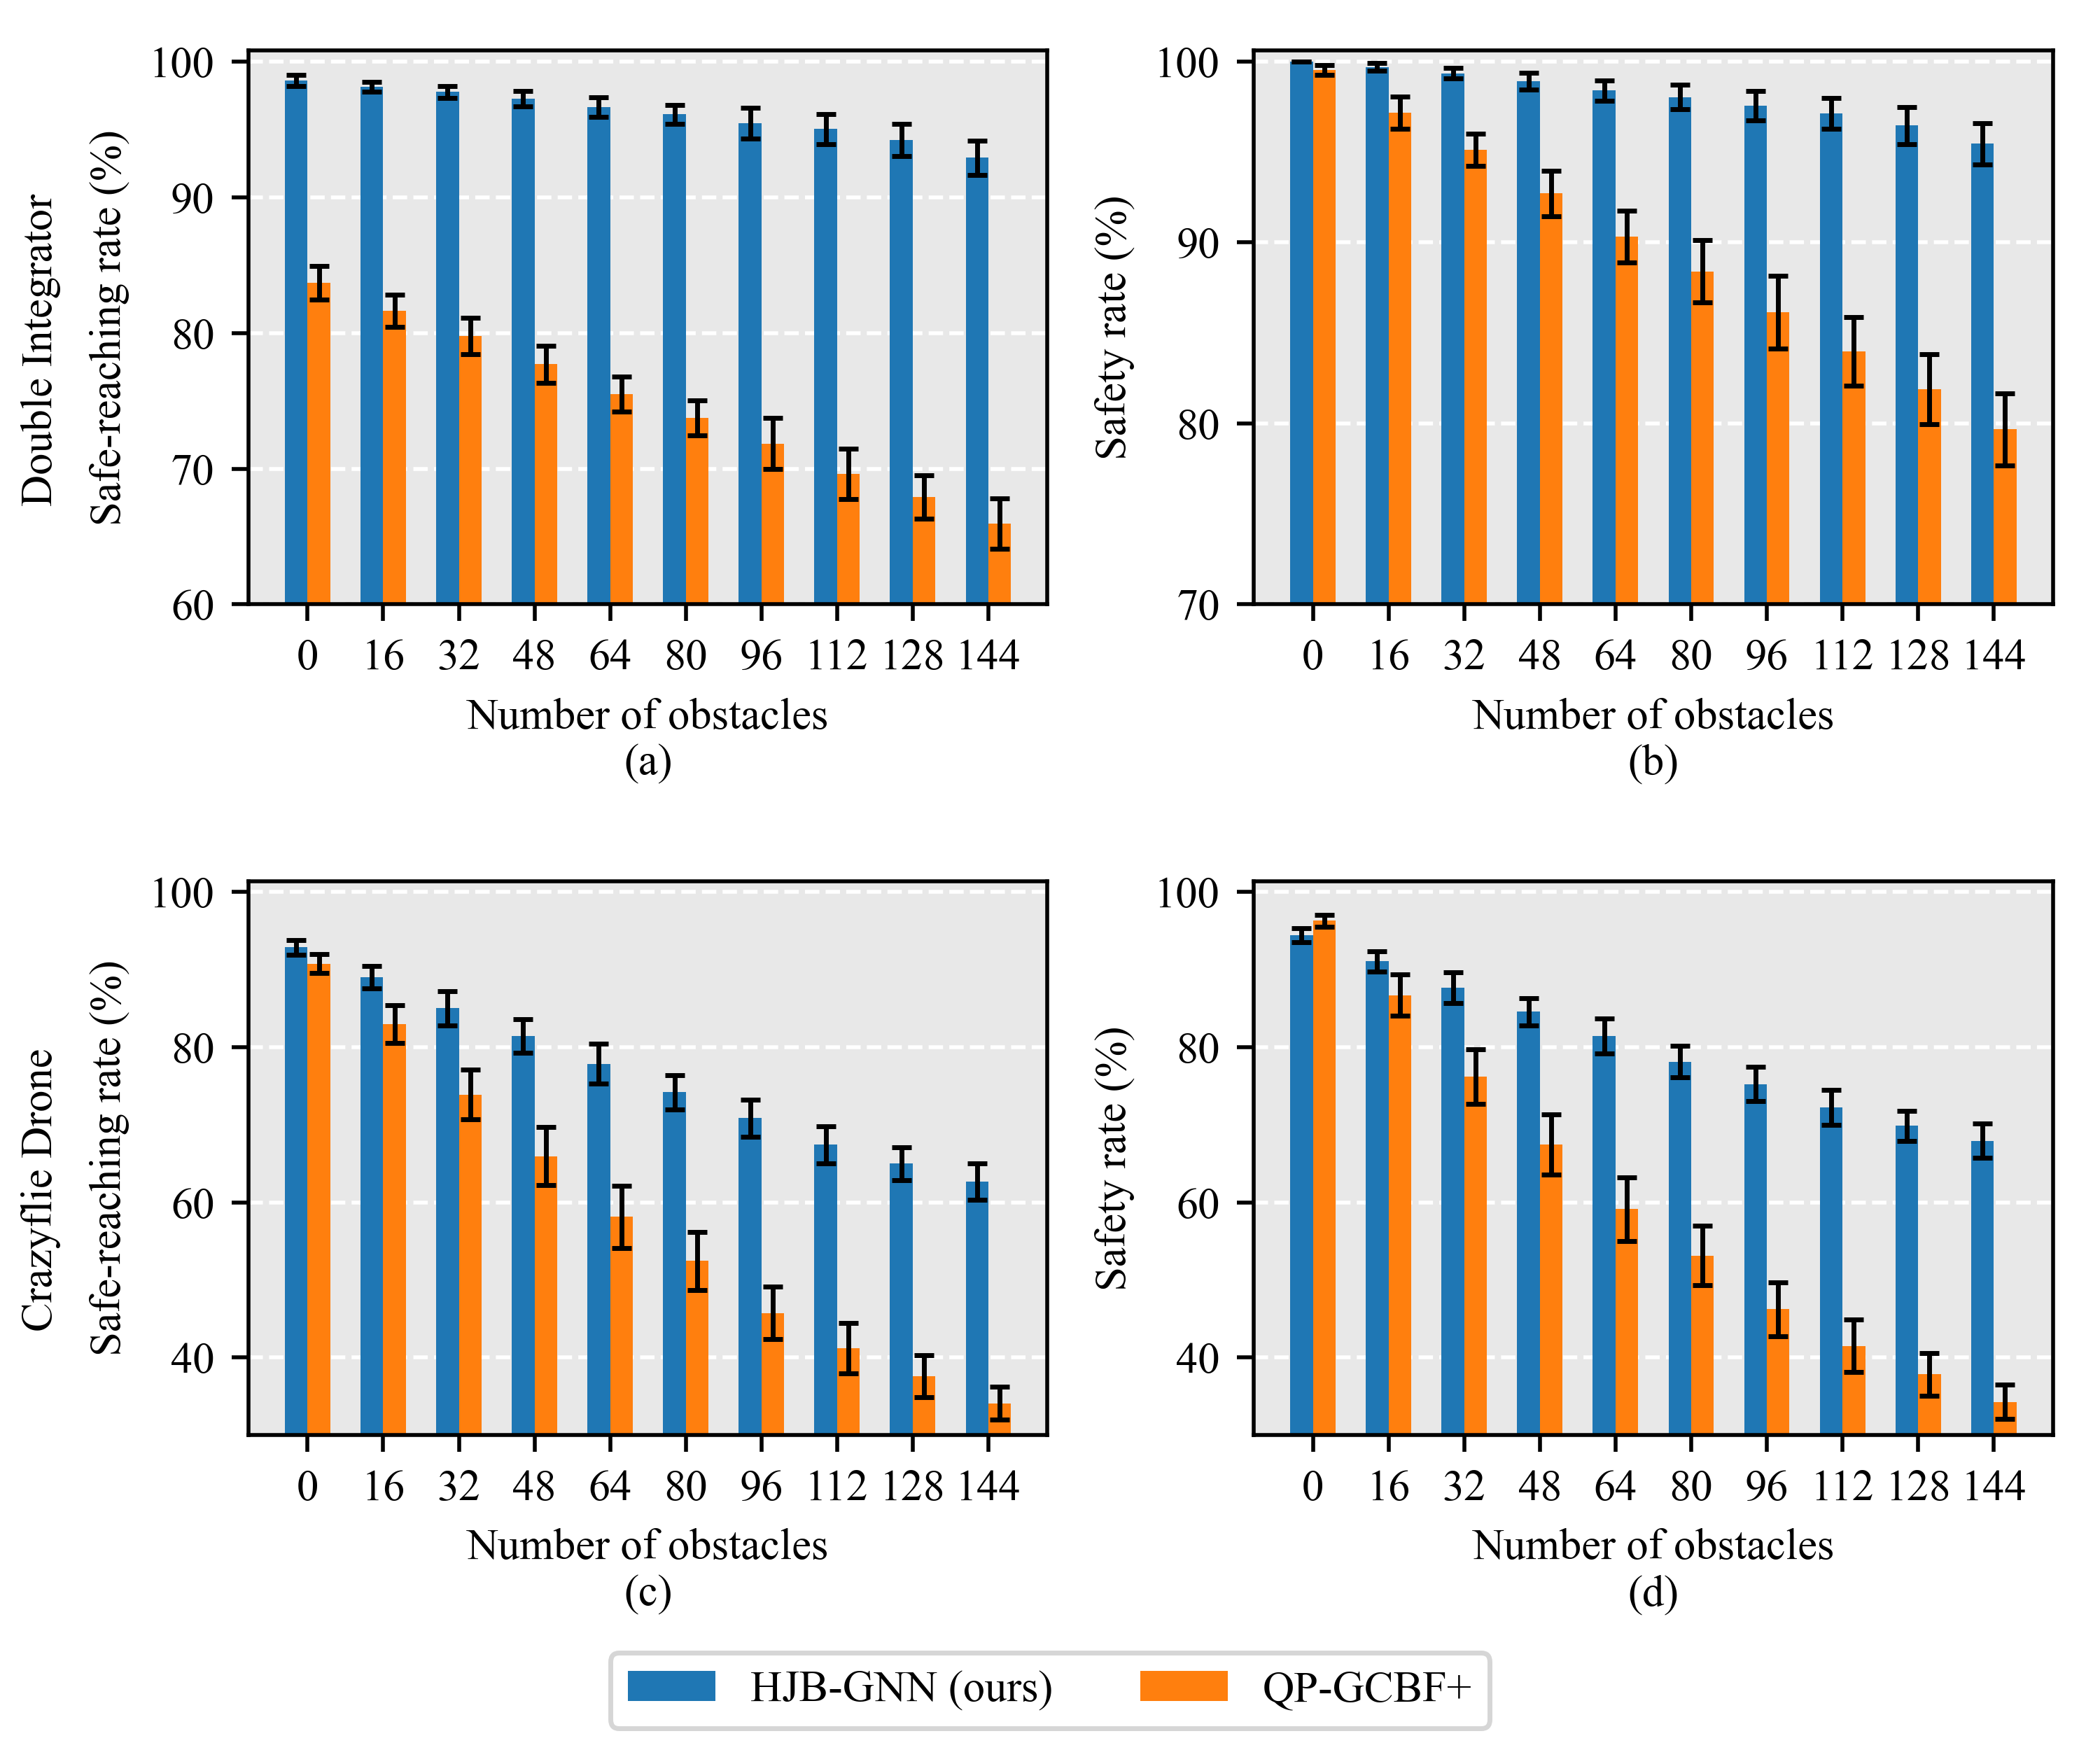
Fig. 6. Safe-reaching rates and safety rates for increasing numbers of obstacles and 1024 agents under fixed area width. (a)-(b): 2D double integrator, and (c)-(d): 3D Crazyflie drone.